OpenAI announced nothing, but its tracking data shows the visible source list of ChatGPT answers collapsing domain by domain. The cause is OpenAI replacing borrowed search results with its own index, and it just invalidated the standard playbook for getting cited.
Between August and September, YouTube lost 91% of its share of ChatGPT’s visible citations. Facebook lost 88.1%, Wikipedia lost 78.4%, and Forbes lost 71.7%. OpenAI said nothing about any of it. The numbers surfaced on September 25 in a LinkedIn post by David Konitzny, a researcher at the GEO platform Peec AI, whose tracking runs hundreds of thousands of branded and non-branded prompts through ChatGPT on a fixed cadence. The next day the data reached r/SEO, where the top practical question, what replaced those sources, went unanswered.
The citation collapse tracks a structural change that Peec AI documented in primary-source research published the same month: ChatGPT has been swapping its retrieval pipeline from Google and Bing results, scraped through third parties, to a family of OpenAI-built indexes internally called Labrador. The domains losing citations are precisely the domains that only looked essential because of the old pipeline. Anyone whose 2026 GEO budget went to Reddit placements, Wikipedia positioning, or YouTube outreach for ChatGPT visibility just watched that thesis expire in a single month.
One month, four cliffs
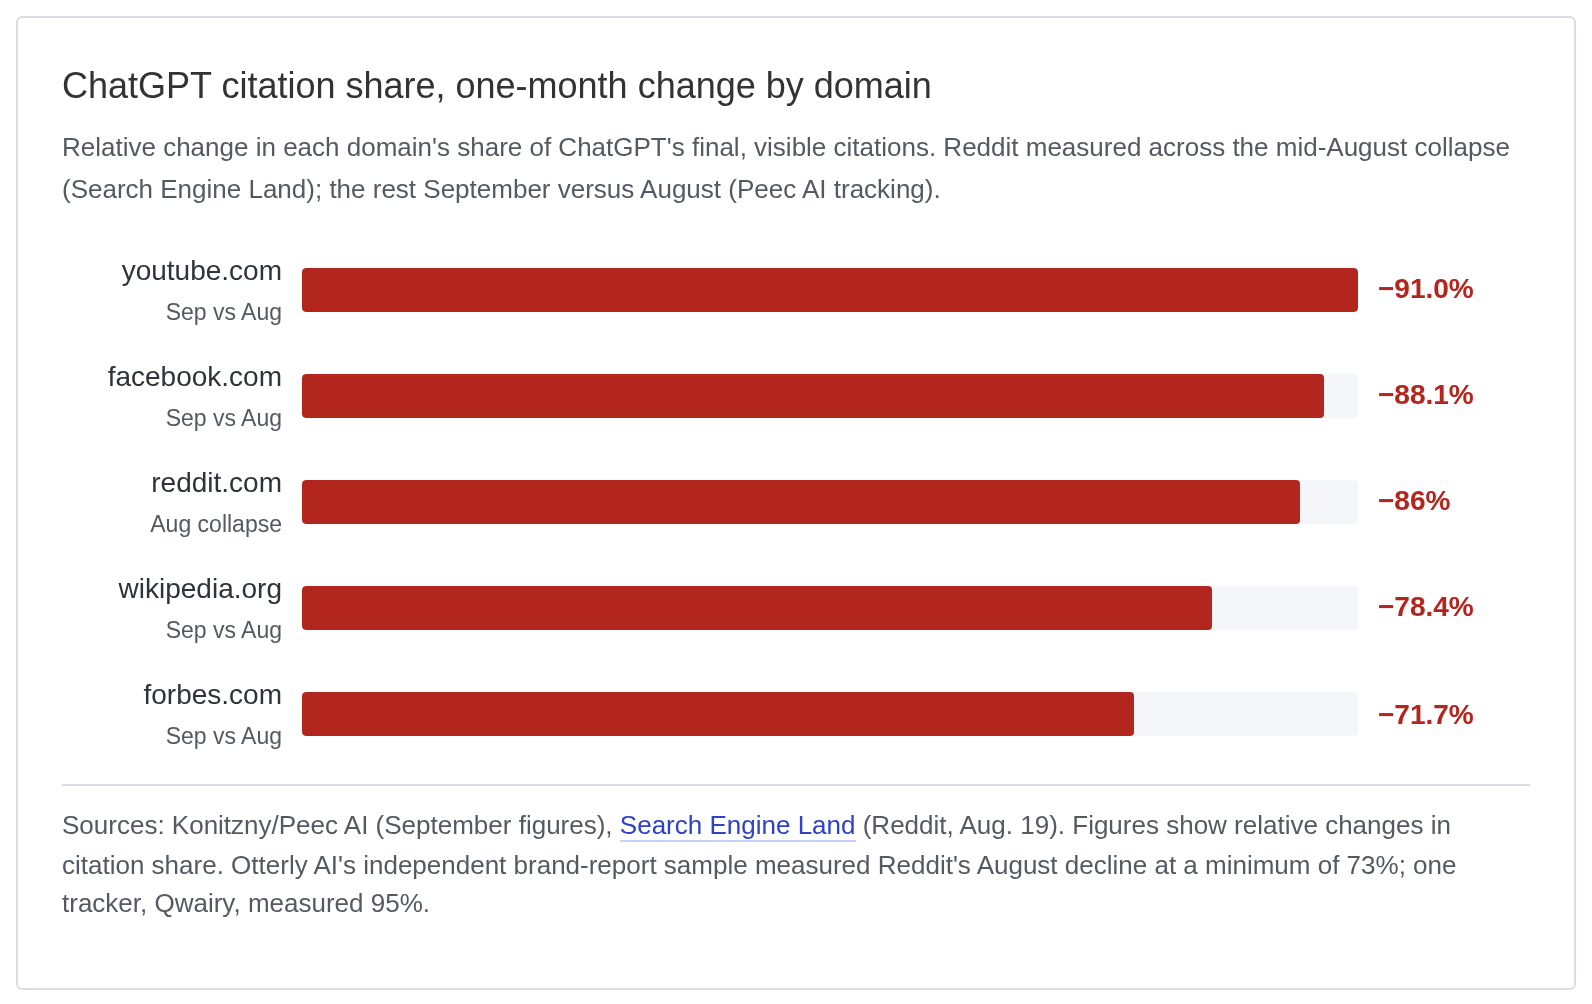
This measures citations: the links ChatGPT prints under an answer. Konitzny’s headline framing, “retrieved does not equal cited,” is the necessary correction; a domain can keep feeding ChatGPT’s answers while disappearing from the attribution. Citation share can also fall for benign methodological reasons, like the engine citing more sources overall. Konitzny checked for that by indexing YouTube’s absolute citation volume against a July baseline and found the drop there too. ChatGPT is citing YouTube less often.
What neither check can rule out is a change in disclosure behavior, with OpenAI retrieving the same sources and showing fewer of them. OpenAI has not commented, and no public statement explains any of these moves. The mechanism described below is the best-evidenced explanation so far.
The August cliff came first
September was not the first cliff, and knowing the August one changes how you read the data. On August 6, OpenAI made GPT-5.6 Luna the default model for ChatGPT’s free users. Within a week, ChatGPT began searching differently; within two, it had largely stopped citing Reddit. Reddit’s share of ChatGPT Search citations ran steady around 3.8% from mid-July, then fell to an average of 0.52% between August 14 and 17, according to Promptwatch tracking reported by Search Engine Land, with Forbes, Axios, and Search Engine Journal covering the drop.
Trackerly, another tracking vendor, watches both the citations ChatGPT prints and the pages it fetches while researching an answer. Through the collapse, roughly one in four pages ChatGPT retrieved was still a Reddit thread, the same ratio as July, per Trackerly’s analysis. OpenAI’s own documentation distinguishes the two lists, the sources consulted and the citations shown. Reddit stopped earning credit and referrals while continuing to shape answers. Ghost source is a fair term for what Reddit became, since its visible influence fell to zero while its actual influence stayed intact.
This is also the second time Reddit has been de-emphasized in a year. Between August and mid-September 2025, Reddit’s presence in ChatGPT answers fell from roughly 60% of tracked responses to around 10% in Semrush’s monitoring, a drop analysts including Kevin Indig tied to Google removing the num=100 parameter, which starved the third-party scraping pipes ChatGPT then relied on. That episode reversed, and by April 2026 Reddit was ChatGPT’s single most-cited domain at 4.14% of citations, per Forbes. The history shows that ChatGPT’s source mix is an operational setting that OpenAI adjusts, repeatedly, without announcement. The 2025 drop had an external cause, Google closing a door. The 2026 pattern has an internal one.
The swap: from borrowed search results to OpenAI’s own index
In early September, Peec AI published primary-source research showing that ChatGPT runs its own retrieval system, internally called Labrador, and that it is not one index but a family of twelve: general web, PDF, YouTube, news (with separate tiers for the last day, the last seven days, and older content), arXiv, Wikipedia, local, finance, legal, medical, shopping, and images. The full investigation is at Peec AI’s blog and docs.peec.ai.
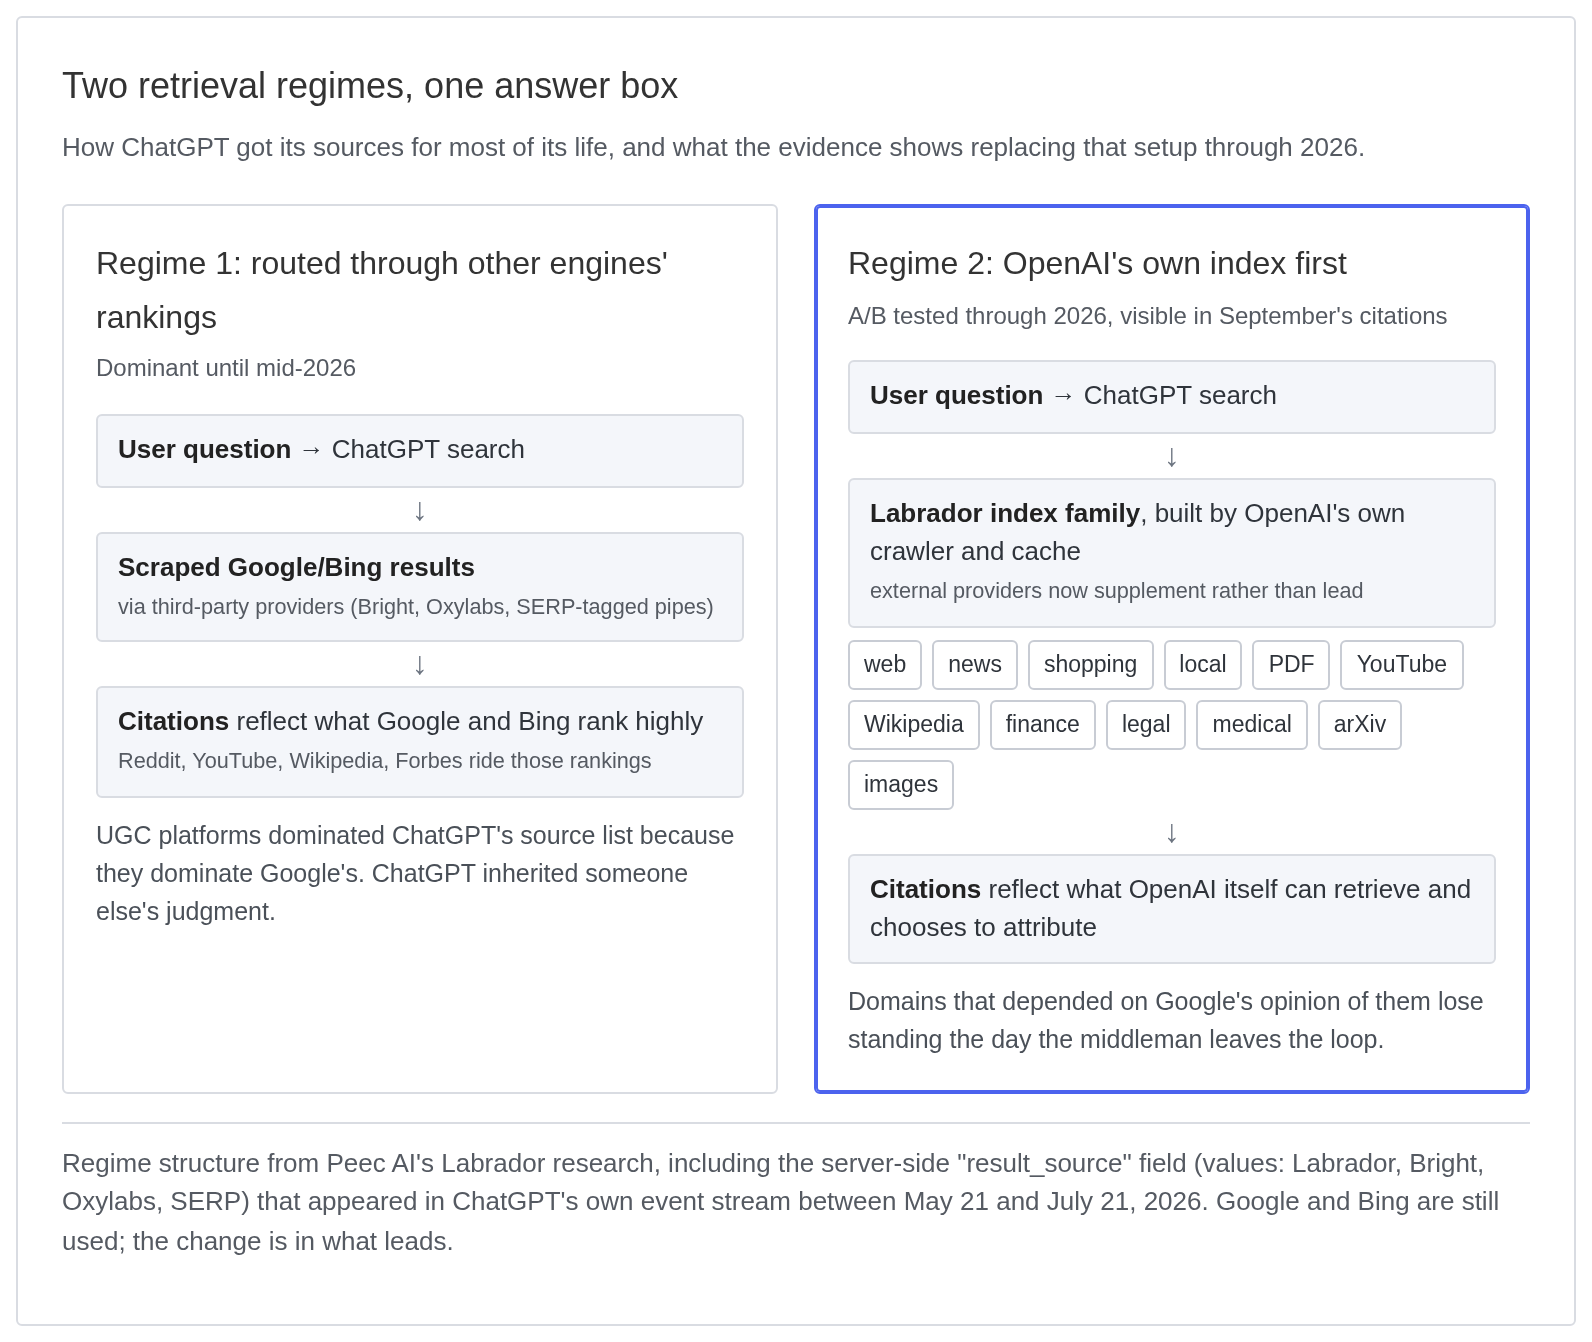
For two months, a field called result_source appeared in ChatGPT’s server-side events carrying only four values: Labrador, Bright, Oxylabs, and SERP. Three are external scraping providers; the first is OpenAI’s own index. OpenAI’s job postings ask for engineers to build “indexing systems, retrieval pipelines, and serving layers” at “exabyte scale,” a hiring push aimed at running the retrieval stack itself. In Google’s antitrust trial, Nick Turley, head of ChatGPT, testified that OpenAI began building its own search index in 2023 after Google refused to license its index, with an early target of answering 80% of queries from it, and that even with full access to Google’s data, five years would be needed just to determine whether full independence is achievable.
The build is already running. Peec AI observed an A/B test named “prefer-index-over-serp-v3” affecting 8% of chats in mid-August, and five separate shopping experiments running against the company’s own index as of September 2. To test crawl capacity, Peec researcher Metehan Yesilyurt published a one-billion-page website as a honeypot; by early September, ChatGPT’s crawler had taken 6 million pages and was still going at roughly 35,000 requests per hour. A cache is confirmed too. In ChatGPT’s lockdown mode, which cannot browse live pages, the system still served current versions of major SEO publications from stored copies. Meanwhile Google and Bing have not been switched off. Peec AI’s CPO Malte Landwehr verified live Google queries by watching a zero-traffic test site get a Google Search Console spike on the exact days he queried ChatGPT about it.
Why the losers lost
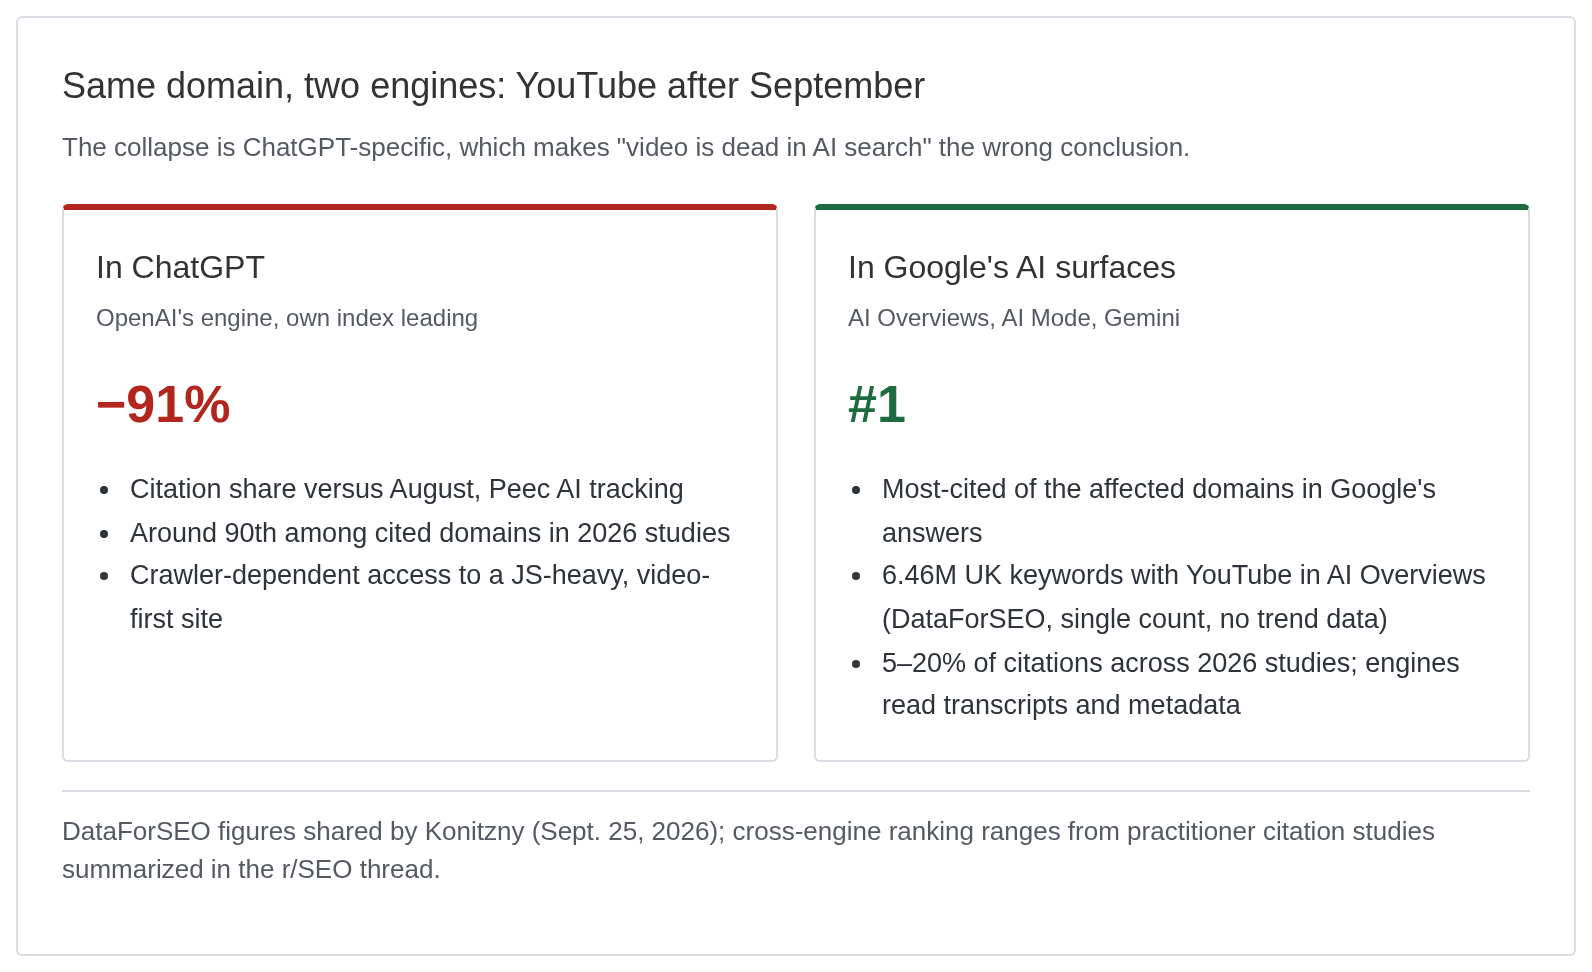
YouTube’s content is mostly video with thin crawlable text; a direct check of youtube.com’s robots.txt shows search results pages disallowed to all bots, and watch pages offer little to a crawler that does not render JavaScript. Google has first-party access to all of it; OpenAI’s crawler does not, and a commenter on Konitzny’s thread put the asymmetry plainly: Google indexes YouTube and Reddit directly, while Bing and Labrador have to crawl and carry far lower coverage of those platforms. Facebook pages are similarly walled off from crawlers. Forbes built a large share of its visibility on ranking in classic search results, exactly the layer being deprioritized.
Wikipedia is the exception that tests the explanation, because Labrador includes a dedicated Wikipedia vertical index. Coverage cannot account for that drop, which makes Wikipedia’s 78% decline evidence that something changed in which retrieved sources get printed as citations, whether a deliberate attribution policy or a disclosure change, and nobody outside OpenAI can say which yet.
What no honest analysis can claim is that these domains have been cut out of answers. Trackerly proved retrieval continued for Reddit; the same is plausible for the rest, and Konitzny explicitly frames his finding that way. The business consequence shifts rather than vanishes. A placement that used to bring a visible citation and a referral visit now brings invisible influence on the answer, which is harder to measure and easier for OpenAI to revoke.
What replaced them
The gain side of the ledger remains unpublished. Konitzny closes his post with “the interesting question is why,” and the practitioner threads asking “what will it cite now” have no data-backed answer yet. What the available evidence supports is directional: citations are consolidating on sources OpenAI can retrieve independently, which means pages its own crawler holds and can verify, without routing through a rival engine’s rankings. Commentary around the data describes the beneficiaries as official brand sites and institutional sources rather than social transcripts.
The collapse is specific to ChatGPT. On Google’s own surfaces, YouTube remains the strongest cited domain of this group. DataForSEO UK data shared in Konitzny’s thread shows YouTube appearing in AI Overviews across 6.46 million keywords, close to twice Wikipedia’s 3.49 million, though that is a count rather than a time series and cannot show a trend. Practitioner citation studies through 2026 consistently place YouTube as the most-cited domain in Gemini, AI Mode, and AI Overviews, at roughly 5% to 20% of citations depending on the study, while ranking around 90th in ChatGPT.
AthenaHQ’s State of AI Search report, released September 29 from millions of responses across eight LLMs, adds the frame: a brand’s own domain goes uncited in 84% of AI answers, and Reddit still supplies 21.9% of off-page citations when all engines are counted together. Grok cites an average of 27 distinct domains per response; Gemini cites five. Any strategy built on “AI search” as a single channel was already wrong before September.
The advice that just expired
The standard GEO playbook of 2025 and 2026 followed the data of its moment: 5W Research found Wikipedia and Reddit together driving over a quarter of US ChatGPT citations in early 2026, with Wikipedia at 13.15% and Reddit at 11.97%; Reddit peaked as ChatGPT’s single most-cited domain in April. Agencies sold placements on exactly those platforms, and through July, the placements worked. The advice failed because it described a pipeline OpenAI was actively replacing, and the data it rested on measured the middleman rather than the engine.
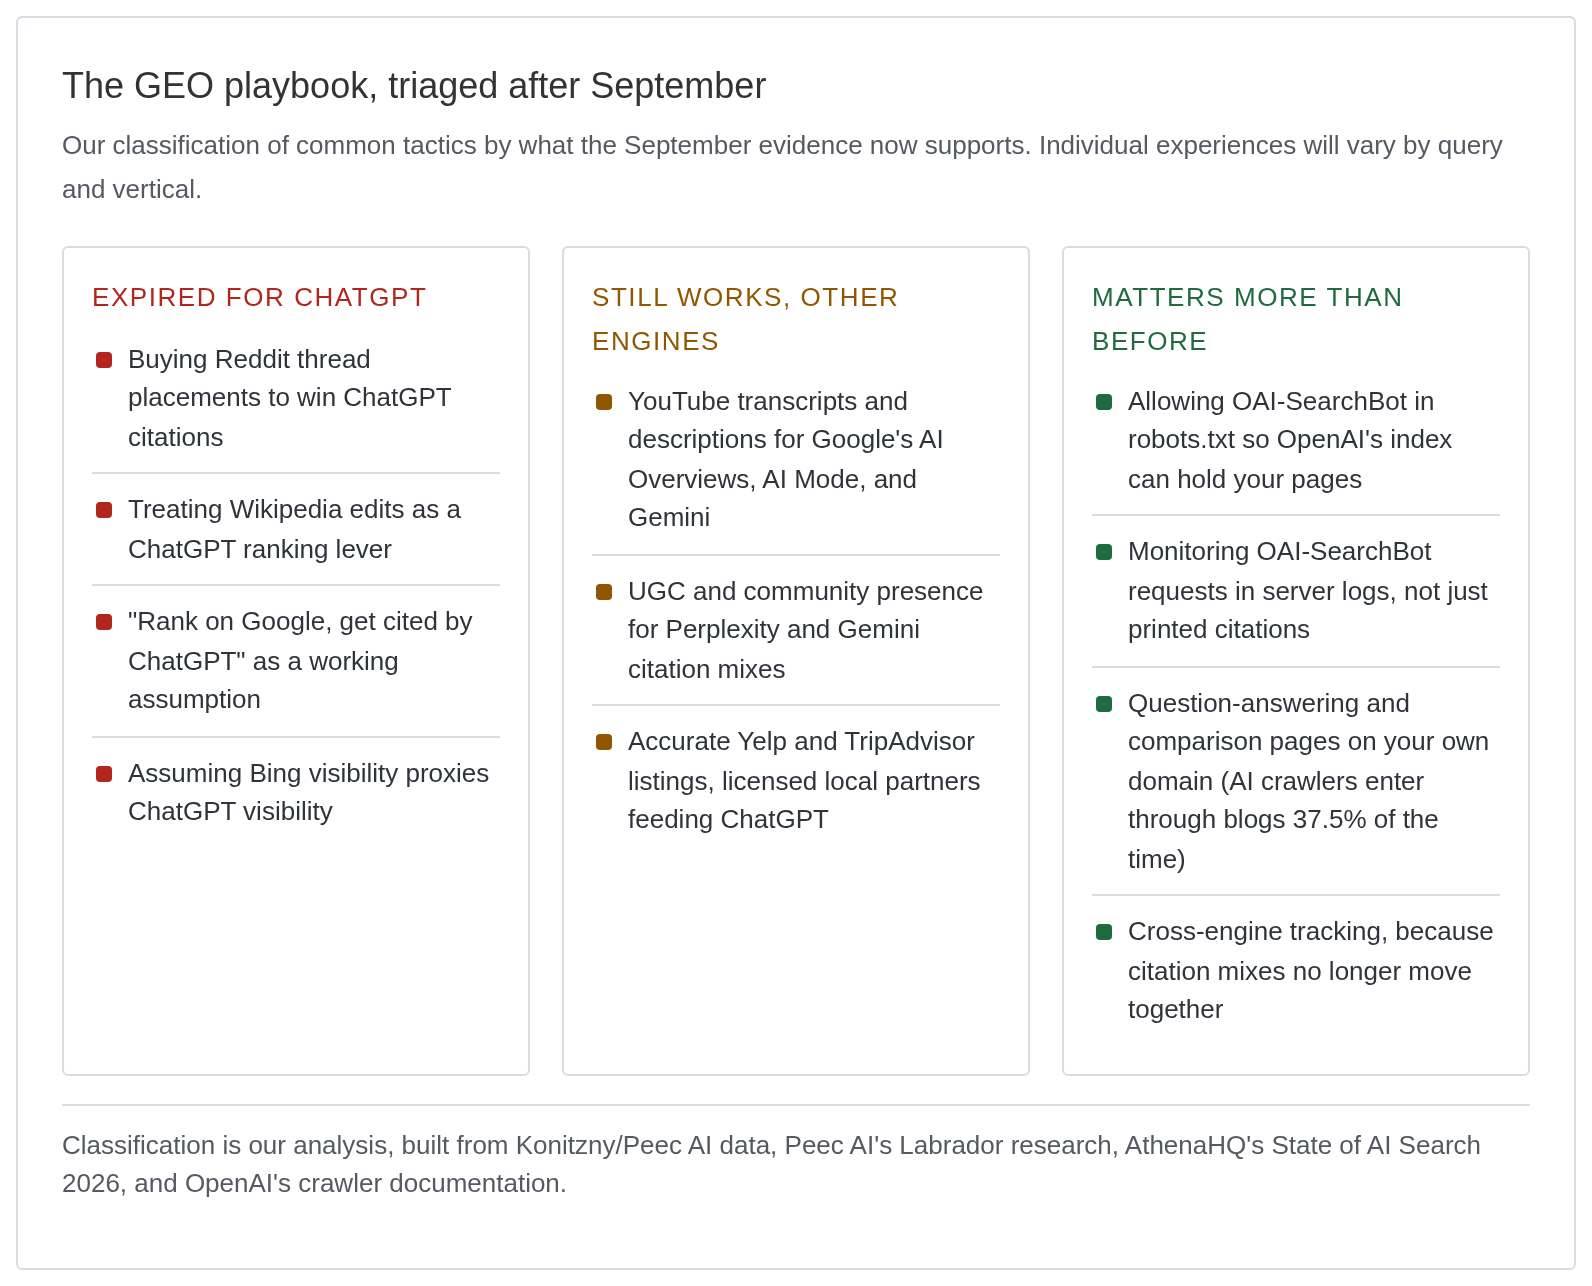
ChatGPT’s source mix has now shifted abruptly in September 2025, May 2026, August 2026, and September 2026, four times in thirteen months, each time without announcement. A tactic whose value depends on one engine’s current preference for a third-party platform has a shelf life measured in months. What survives regime changes is being crawlable by each engine’s own crawler and being the primary source for the facts about your own business.
The ten-minute audit
If you run a small business and this reads like insider noise, one audit covers it. OpenAI publishes exactly which crawler controls ChatGPT visibility, and it is not the one most sites have been managing.
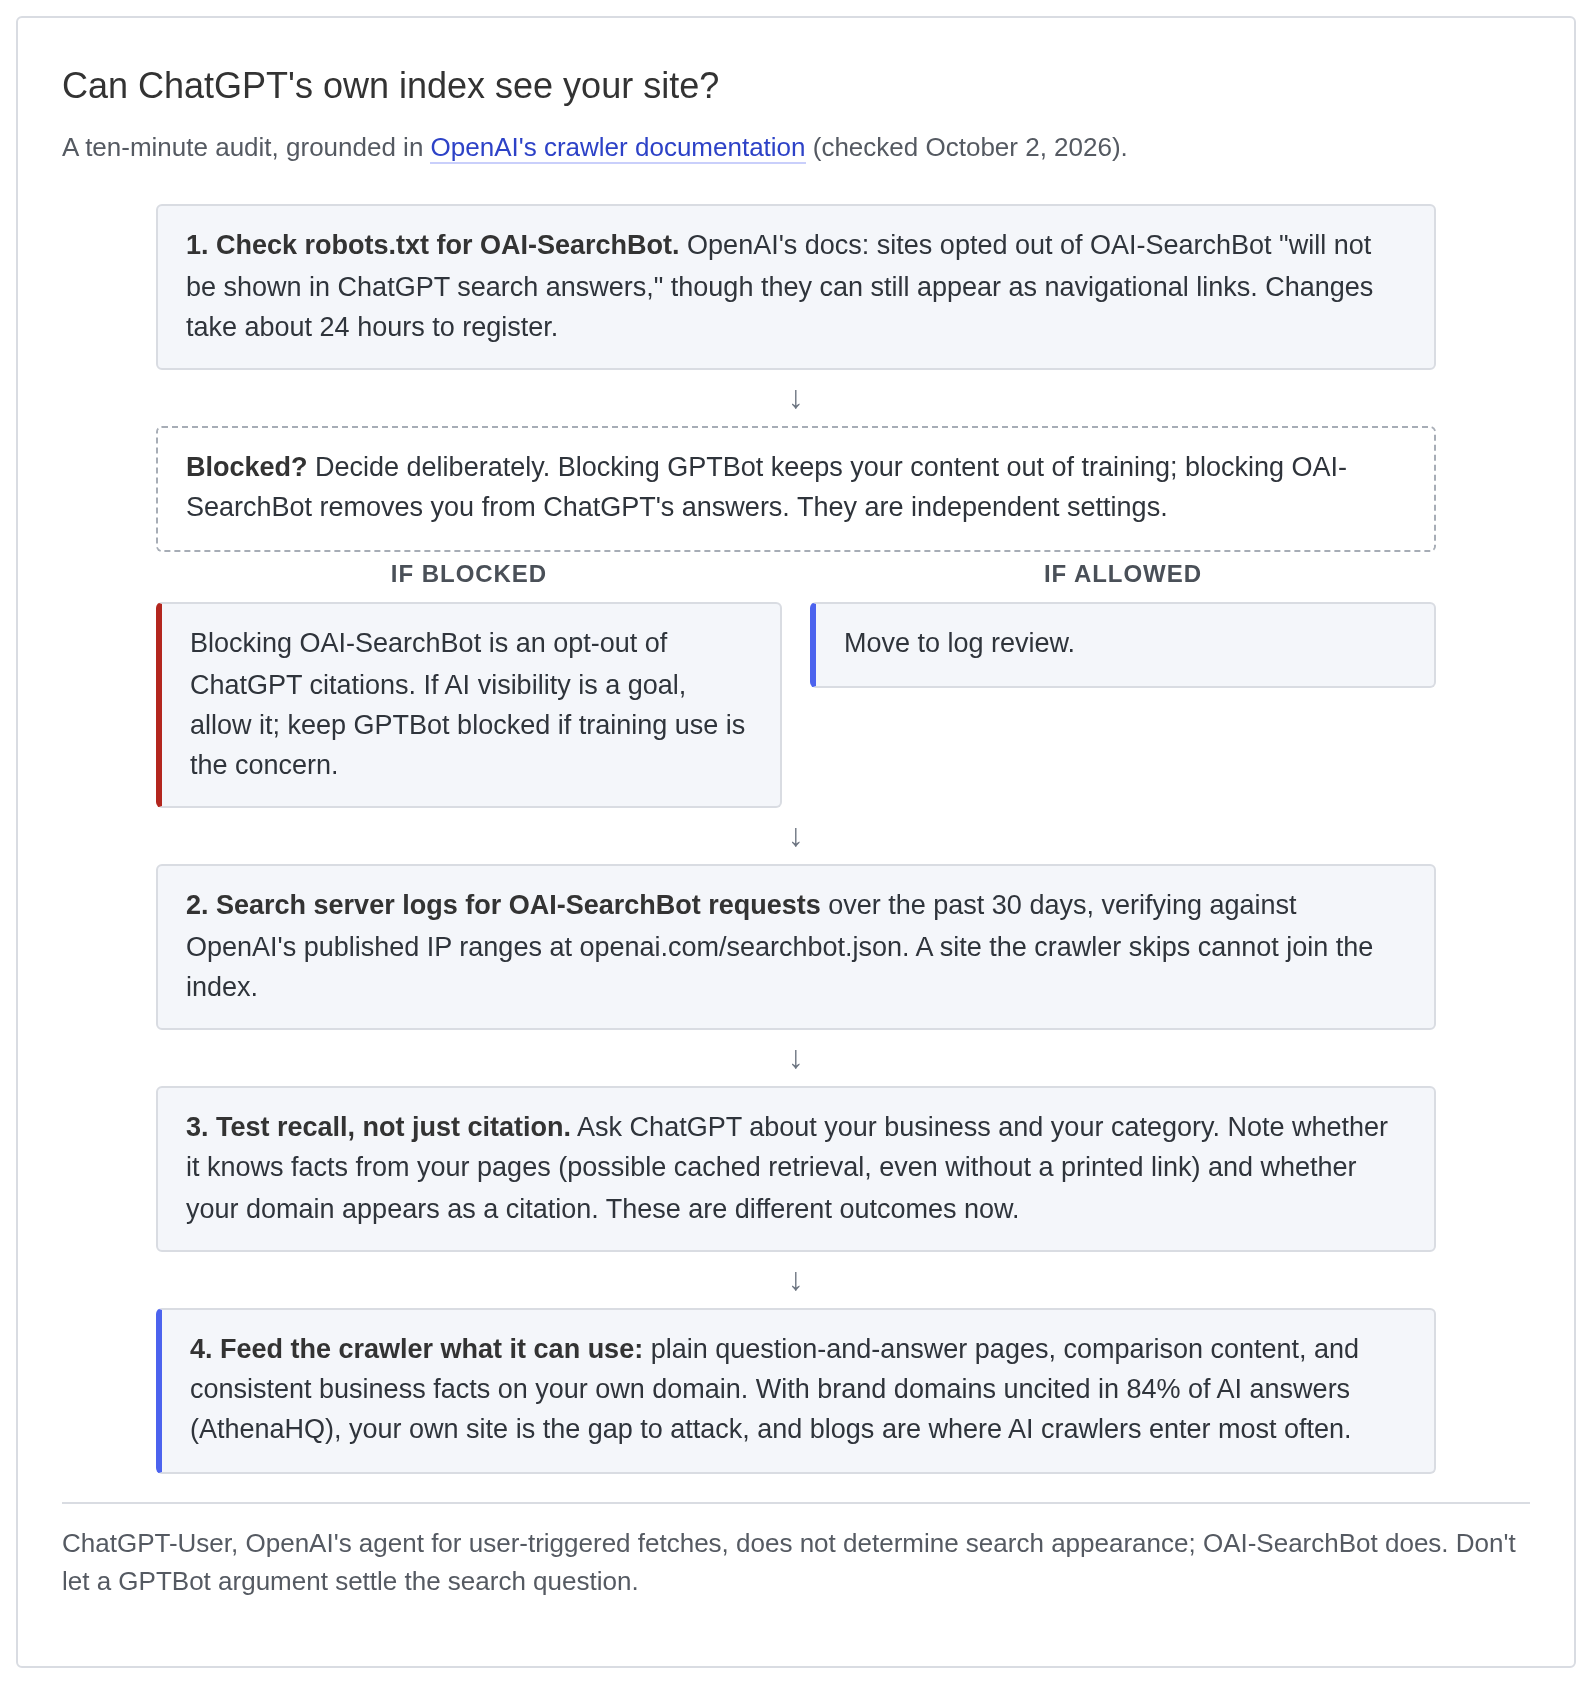
For practitioners, the measurement upgrade matters as much as the tactics. Citation trackers see only what OpenAI prints, and OpenAI has now shown twice in two months that printing and reading can decouple. The retrieval layer shows up in server logs for OAI-SearchBot, ChatGPT-User, and GPTBot, while citation tracking covers only the attribution layer. The strategy should watch both. And because engines no longer move together, a ChatGPT decline is not a signal to abandon YouTube work that serves Google’s surfaces, or Reddit work that serves Perplexity. The single-channel GEO retainer has been replaced by engine-by-engine management with retrieval monitoring underneath.
The direction of travel
Turley’s testimony supplies the horizon: full independence from outside search providers is “not something you switch on,” and OpenAI’s own estimate was five years to learn whether 100% is even achievable. So the September diet change is one monthly reshuffle in a multi-year migration, and the shopping experiments still running in production show OpenAI testing its index against borrowed results one vertical and one query type at a time.
For everyone whose visibility depends on these answers, that converts the lesson into a standing rule. The winners and losers of AI citations are now decided by whoever controls the index doing the retrieving, and that control is changing hands while the industry watches. Budget for monitoring, keep your own site crawlable and quotable, and treat any playbook older than one quarter as unproven until current data supports it.
Sources
- David Konitzny (Peec AI), “ChatGPT is falling out of love with YouTube”, LinkedIn, Sept. 25, 2026. September citation-share declines and absolute-volume check.
- WebLinkr, “ChatGPT stopped Citing YouTube in September”, r/SEO, Sept. 26, 2026, including DataForSEO UK figures and cross-engine discussion.
- Peec AI, “ChatGPT built its own search index” and docs.peec.ai research notes, September 2026. Labrador index family, result_source field, A/B tests, crawler honeypot, cache tests, Turley testimony.
- Matt G. Southern, “Reddit’s ChatGPT Search citations fell 86% in four days”, Search Engine Land, Aug. 19, 2026.
- Trackerly, “ChatGPT 5.6 Still Reads Reddit, It Just Stopped Citing It”, Aug. 20, 2026. Retrieved-versus-cited evidence and the 2025 precedent.
- AthenaHQ, State of AI Search 2026, GlobeNewswire, Sept. 29, 2026. 84% brand-domain uncited rate; Reddit 21.9% of off-page citations; Grok vs Gemini domain counts; blog entry-point share.
- OpenAI, “Overview of OpenAI Crawlers”, checked Oct. 2, 2026. OAI-SearchBot, GPTBot, ChatGPT-User, OAI-AdsBot roles and the 24-hour robots.txt propagation note.
- 5W Research via PR Newswire, “Wikipedia and Reddit Now Drive Over 25% of ChatGPT Citations in the US”, May 11, 2026.
- YouTube, robots.txt, fetched Oct. 2, 2026. Crawl-surface check.
- Search Engine Journal, “Why Reddit’s ChatGPT Citation Drop Isn’t Fully Explained”, Aug. 19, 2026. Competing explanations for the August drop.
Figures attributed to vendors (Peec AI, Promptwatch, Otterly, Qwairy, DataForSEO, AthenaHQ) come from those companies’ own tracking products; each has a commercial interest in GEO measurement. OpenAI has issued no public statement on any of these changes as of October 2, 2026.